VMware Cloud Foundation

 View Only
  • 1.  VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 12, 2026 01:13 PM

    I have deployed a Greenfield VCF 9.1 management domain. The VCF installer fails at "Deploy and configure VCF Management Platform" 14/15

    Subtask: Configure Lifecycle Components

     The request to configure the Fleet lifecycle failed. <unknown error> Reference Token: KEIOTA
    The following VMs are deployed in my management vCenter
    I can access NSX Manager, SDDC manager and vCenter with no issues.
    Any guidance or direction to resolve this would help to progress the deployment


  • 2.  RE: VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 12, 2026 10:40 PM

    Hi MrHMoha,

    The generic Reference Token doesn't expose the actual root cause in the installer UI. 
    I'd first check the Fleet Lifecycle logs before retrying the workflow.
     
    Verify the following:

    1. Confirm forward and reverse DNS resolution for SDDC Manager, vCenter, NSX Manager, and all vcf-svc-* appliances. Test resolution from both SDDC Manager and the management-service appliances.

    2. Confirm time synchronization is consistent across all appliances. Certificate and authentication calls can fail when there is significant clock drift.

    3. Validate TCP connectivity between SDDC Manager and the VCF lifecycle/management appliances, particularly ports 443 and 22. Broadcom has documented similar Fleet deployment failures caused by missing routes or blocked connectivity.

    4. Check the lifecycle log for the Reference Token KEIOTA and review the preceding exception:

    grep -i -B 20 -A 50 "KEIOTA" /var/log/vrlcm/vmware-vrlcm.log

    Depending on the appliance layout, also search:

    grep -Ri "KEIOTA" /var/log /storage/log 2>/dev/null

    5. Check whether the VCF Management Services and lifecycle-related services are healthy before clicking Retry. Avoid deleting or manually recreating the vcf-svc-* VMs, since they may already be registered in the deployment database.

    You can also generate a Fleet Management support bundle from:
    VCF Operations → Fleet Management → Lifecycle → VCF Management → Settings → Logs
     
    or from the appliance CLI:
    mkdir -p /data/fleetmanagement-logbundle /var/lib/vlcm-common/vlcm-support \ -w /data/fleetmanagement-logbundle
    Broadcom documents this as the supported method for collecting the Fleet Lifecycle logs.
     
    Once the underlying DNS, routing, certificate, credential, or service error is corrected, use Retry in the installer rather than restarting the full management-domain deployment.
     
    Since this is VCF 9.1 and the UI only reports an unknown error, I'd also open a Broadcom support case and attach the installer bundle, Fleet Management bundle, Reference Token, and exact failure timestamp. Some VCF 9.1 Fleet Lifecycle failures are currently documented as known issues that require Support intervention.


  • 3.  RE: VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 14, 2026 01:58 AM

    Restarting fleet lcm service will resolve this failed task.

    This has been previously answered here.
    https://community.broadcom.com/vmware-cloud-foundation/discussion/vcf-91-installation-lifecycle-component-issue#bmc5fadc5e-e14d-4c2a-b405-019e9b88ec39

    If you resolve your issue with this response, then please mark it Recommend for other to find it as well, thanks!


    ------------------------------
    Abbed Sedkaoui
    vExpert VCF 2026
    https://vexpert.vmware.com/directory/10999
    ------------------------------


  • 4.  RE: VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 22, 2026 12:47 AM

    Hi Abbed,

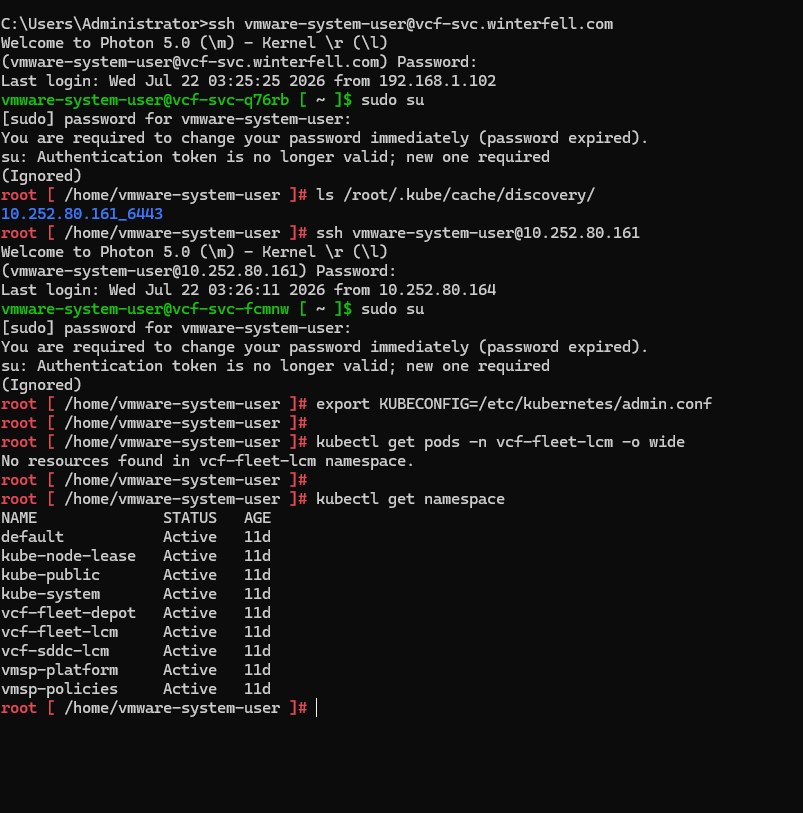
    I have followed the below as suggested thread, however it seems no pods exist under the namespace vcf-fleet-lcm. FYI it has not reached the stage to deploy VCF Ops

    Restarting fleet lcm service will resolve this failed task.

    This has been previously answered here.
    https://community.broadcom.com/vmware-cloud-foundation/discussion/vcf-91-installation-lifecycle-component-issue#bmc5fadc5e-e14d-4c2a-b405-019e9b88ec39

    Any ideas for the next steps to resolve this please?


  • 5.  RE: VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 22, 2026 10:29 PM
    Edited by Mark Koh Jul 29, 2026 02:03 AM

    Hi Mohamed,

    I have followed the below as suggested thread, however it seems no pods exist under the namespace vcf-fleet-lcm. FYI it has not reached the stage to deploy VCF Ops.

    You are right vcf-fleet-lcm is deployed before VCF Ops and from the image you have it successfully deployed 7/10/2026 at 11:14AM, 
    then there is a time blank in the UI until 4:41PM the same day show the start of the Configure lifecycle Components subtask and then the <unknown error> (ie: not even an error handled by the code).

    If this is Production environment the best advice like was previously said here to generate a Fleet Management support bundle via the arrow under admin@local in VCF Installer.
    techdocs ref: https://techdocs.broadcom.com/us/en/vmware-cis/vcf/vcf-9-0-and-later/9-1/deployment/deploying-a-new-vmware-cloud-foundation-or-vmware-vsphere-foundation-private-cloud-/troubleshooting-vmware-cloud-foundation-or-vmware-vsphere-foundation-deployments.html

    I did it with fleet management select and it generated an sos tar.gz of 167MB. You can share it to Broadcom Support if can open a case.

    That said it doesn't hurt to get more information.

    First sanity check of Kubernetes critical trio: DNS, NTP, k8s node kubelet service

    1. DNS: used by Kubernetes to create certificates for services
    "platformFqdn":
    "instanceFqdn":
    "fleetFqdn":
    ref: https://developer.broadcom.com/xapis/vcf-installer-api/latest/data-structures/SddcVspClusterSpec/
    Note i used Windows active directory and my "vspClusterSpec" json looks as follow

        "vspClusterSpec": {
            "ipv4Pool": {
                "ipRange": {
                    "startIpAddress": "172.30.0.33",
                    "endIpAddress": "172.30.0.xx"
                }
            },
            "platformFqdn": "vcf9-vsp01.abidi.systems",
            "instanceFqdn": "vcf9-ic01.abidi.systems",
            "fleetFqdn": "vcf9-opsfm01.abidi.systems",
            "systemUserPassword": "*****",
            "size": "small",
            "name": "vcf-m01-vmsp-01",
            "internalClusterCidrIpv4": "198.18.0.0/15"
        },


    2. NTP: used by Kubernetes Probes (StartupProbes, LivenessProbes, ReadinessProbes) that has timeout in seconds
    - verify the last sync in every vSphere node if no last sync visible then stop and restart ntpd service of said ESXi from vCenter
    3. VMSP k8s node kubelet service: used by Kubernetes Worker node to communicate, with Master node API server, the state of everything in K8s
    - `system status kubelet`

    Note on naming: vSphere nodes are ESXi host but VMSP K8s nodes are VMs like VKS Supervisor VMs and VKS Cluster nodes are also K8s nodes

    Connect VMSP Cluster again if not already done
    export KUBECONFIG=/etc/kubernetes/admin.conf

    4. Node status
    kubectl get nodes -o wide

    5. Cluster Warning events 
    kubectl events -A --types=Warning

    6. Pod status not running or completed
    kubectl get pod --field-selector=status.phase!=Running,status.phase!=Succeeded -A


    ------------------------------
    Abbed Sedkaoui
    vExpert VCF 2026
    https://vexpert.vmware.com/directory/10999
    ------------------------------


  • 6.  RE: VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 27, 2026 12:44 AM

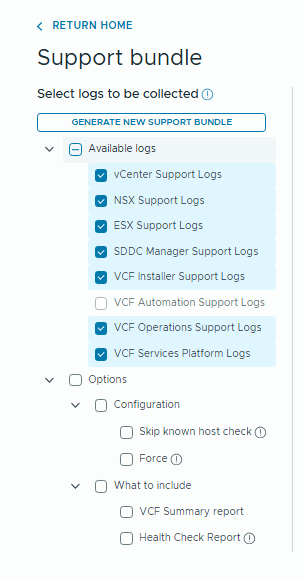
    There doesn't appear to be an option to select Fleet Management and generate a .tar.gz file. In any case, this is a homelab environment, so I'm unable to share the logs with Broadcom for analysis.

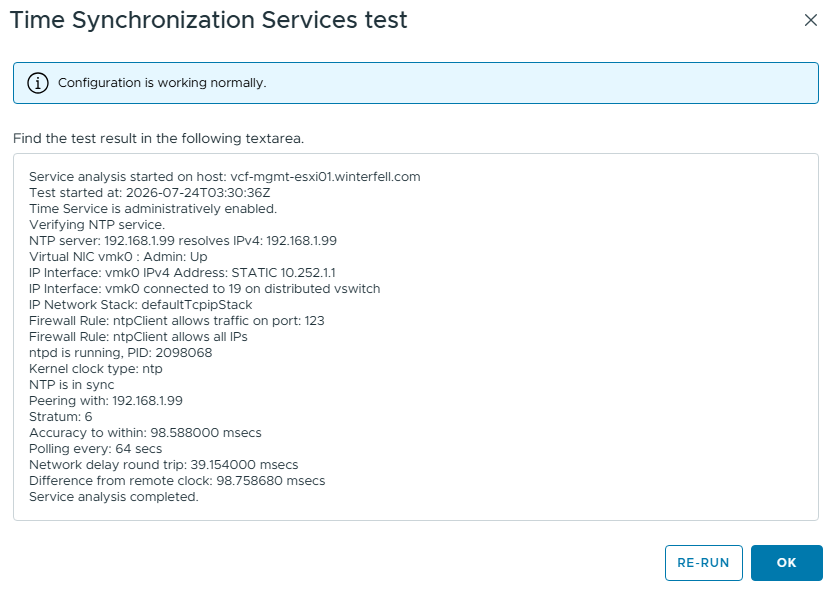
    I have checked the NTP config which is configured successfully and working on the mgmt hosts which the k8s nodes are running on 

    All 4 management hosts NTP Configuration is working normally
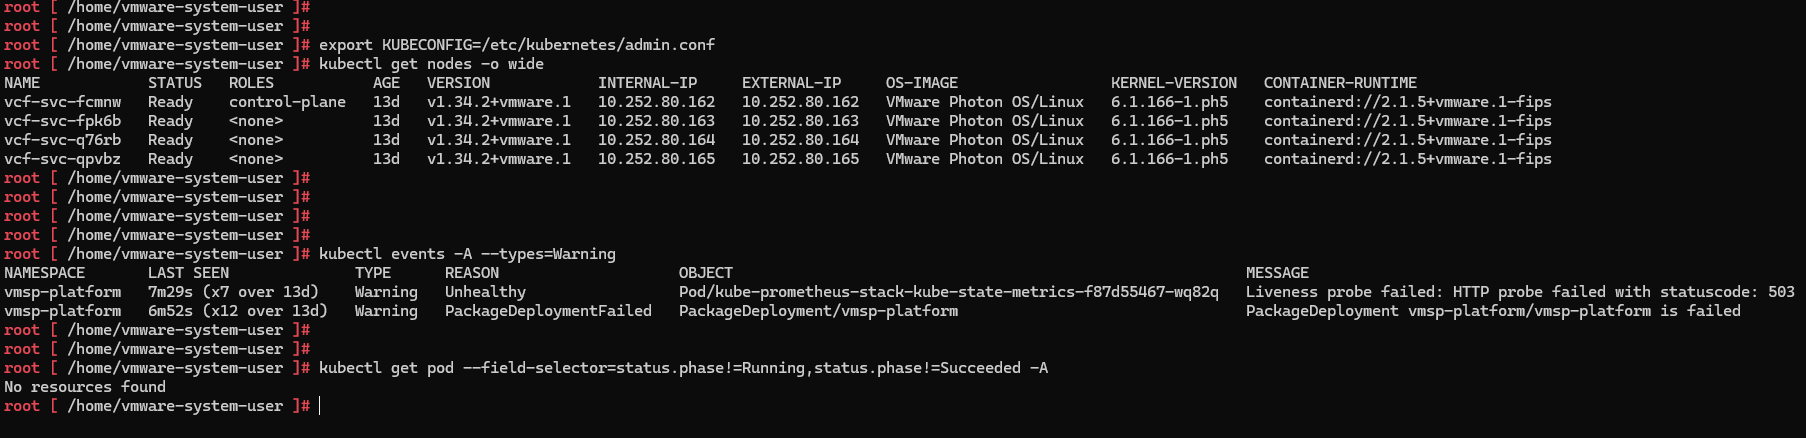
    root [ /home/vmware-system-user ]# export KUBECONFIG=/etc/kubernetes/admin.conf
    root [ /home/vmware-system-user ]# kubectl get nodes -o wide
    NAME            STATUS   ROLES           AGE   VERSION            INTERNAL-IP     EXTERNAL-IP     OS-IMAGE                 KERNEL-VERSION   CONTAINER-RUNTIME
    vcf-svc-fcmnw   Ready    control-plane   13d   v1.34.2+vmware.1   10.252.80.162   10.252.80.162   VMware Photon OS/Linux   6.1.166-1.ph5    containerd://2.1.5+vmware.1-fips
    vcf-svc-fpk6b   Ready    <none>          13d   v1.34.2+vmware.1   10.252.80.163   10.252.80.163   VMware Photon OS/Linux   6.1.166-1.ph5    containerd://2.1.5+vmware.1-fips
    vcf-svc-q76rb   Ready    <none>          13d   v1.34.2+vmware.1   10.252.80.164   10.252.80.164   VMware Photon OS/Linux   6.1.166-1.ph5    containerd://2.1.5+vmware.1-fips
    vcf-svc-qpvbz   Ready    <none>          13d   v1.34.2+vmware.1   10.252.80.165   10.252.80.165   VMware Photon OS/Linux   6.1.166-1.ph5    containerd://2.1.5+vmware.1-fips
    root [ /home/vmware-system-user ]#
    root [ /home/vmware-system-user ]#
    root [ /home/vmware-system-user ]#
    root [ /home/vmware-system-user ]#
    root [ /home/vmware-system-user ]# kubectl events -A --types=Warning
    NAMESPACE       LAST SEEN              TYPE      REASON                    OBJECT                                                         MESSAGE
    vmsp-platform   7m29s (x7 over 13d)    Warning   Unhealthy                 Pod/kube-prometheus-stack-kube-state-metrics-f87d55467-wq82q   Liveness probe failed: HTTP probe failed with statuscode: 503
    vmsp-platform   6m52s (x12 over 13d)   Warning   PackageDeploymentFailed   PackageDeployment/vmsp-platform                                PackageDeployment vmsp-platform/vmsp-platform is failed
    root [ /home/vmware-system-user ]#
    root [ /home/vmware-system-user ]#
    root [ /home/vmware-system-user ]# kubectl get pod --field-selector=status.phase!=Running,status.phase!=Succeeded -A
    No resources found
    root [ /home/vmware-system-user ]#
     

    Any pointers on where to go next would be greatly appreciated, I'm struggling to see the best way forward now. I feel like I've hit a wall with this build.

    Just to add, I redeployed the lab using a new VCF Installer and new management hosts, but I ended up getting stuck on the same task again. 😞


  • 7.  RE: VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 27, 2026 11:03 PM

    Hello MrHMoha,

    Since the vcf-fleet-lcm namespace isn't present, it suggests the failure is occurring before the Fleet Lifecycle Kubernetes services are fully initialized, which is why restarting the Fleet LCM service isn't having any effect.
     
    At this point I'd verify a few additional items:
     
    1. Forward and reverse DNS for all management component FQDNs (platformFqdn, instanceFqdn, fleetFqdn). Make sure the reverse lookup returns the expected hostname and not a generic or different record. Several VCF 9.1 deployment issues have ultimately been traced back to DNS/SAN mismatches.
     
    2. From SDDC Manager, confirm you can resolve and connect to every management FQDN:
     
    nslookup <fqdn>
    dig -x <ip>
     
    3. Check whether the deployment created the VCF Management Platform services at all:
     
    kubectl get ns
    kubectl get pods -A
     
    If the Fleet namespace was never created, the failure likely happened during the bootstrap phase rather than during Fleet initialization.
     
    4. Review the SDDC Build Service logs around the failure timestamp. The UI only reports the generic reference token, but the build-service logs usually contain the first Java exception that explains what actually failed.
    5. If you're using Active Directory DNS, double-check that there are no duplicate A/PTR records or stale entries from previous deployment attempts. Even in a homelab, stale DNS records can cause certificate validation failures during the initial bootstrap.
     
    One question: Was this deployment completely greenfield, or was the same host/IP/FQDN combination used in a previous failed deployment? Residual DNS records or leftover inventory from an earlier attempt can sometimes produce exactly this type of bootstrap failure before Fleet Lifecycle is fully deployed.


  • 8.  RE: VCF 9.1 Deployment fails at Deploy and configure VCF Management Platform ( The request to configure the Fleet lifecycle failed)

    Posted Jul 29, 2026 01:18 AM

    Yeah VCF Services Platform Logs that's the name that contains infos on fleet-lcm, i did it 70 days ago.
    Anyway download the sos tar.gz for these logs even of failed deployment are valuables learning informations.

    Comparing the duration of these subtasks, deployment of lifecycle took 20min for me on nested ESXi

    image

    image

    Although they both deployed successfully, in your case it took x3 more times and,
    then something happened after without vcf installer UI knowledge from 11h14AM to 4h41PM on 7/10/2026.
    It maybe worth looking at domainmanager.log from VCF Installer in this time frame.
    Remember that log have time in UTC+0 so also look for the successful deployment of lifecycle.

    The warning show 'PackageDeployment vmsp-platform/vmsp-platform is failed',
    this PackageDeployment is not single kubernetes deployment but many of them using a tool called helm.
    You can think helm like linux apt, yum, or dnf, they are package management

    Because VMSP contains many resources so it's not as simple like deleting a single pod.

    Next what you point out, having an another VCF deployment stuck at the same task is new information.

    It's worth looking again for:
    - DNS A and PTR records
    - misconfiguration in the json deployment spec

    If you have not saved the json deployment spec, then you can retrieve it like this: 
    - from domainmanager.log in VCF Installer (I use WinSCP to copy over the file)
    - look for sddcId
    - copy everything between the curly braces {}
    - paste it on notepad++
    - from Plugin menu -> Plugin admin
    - search JSTool -> install
    - from Plugin menu -> JSTool -> JSFormat
    will restore the json from the log in its original states.
    What come to my mind is maybe there is not enough IP in the VMSP ip pool.

    An another Tips: you can use this technique to make clear every json like for example error code 50x in apiserver audit log in the sos tar.gz


    ------------------------------
    Abbed Sedkaoui
    vExpert VCF 2026
    https://vexpert.vmware.com/directory/10999
    ------------------------------